African Language AI Insights
Practical insights on African speech data, ASR development, African language IVR, and CPaaS for African markets.
Latest articles
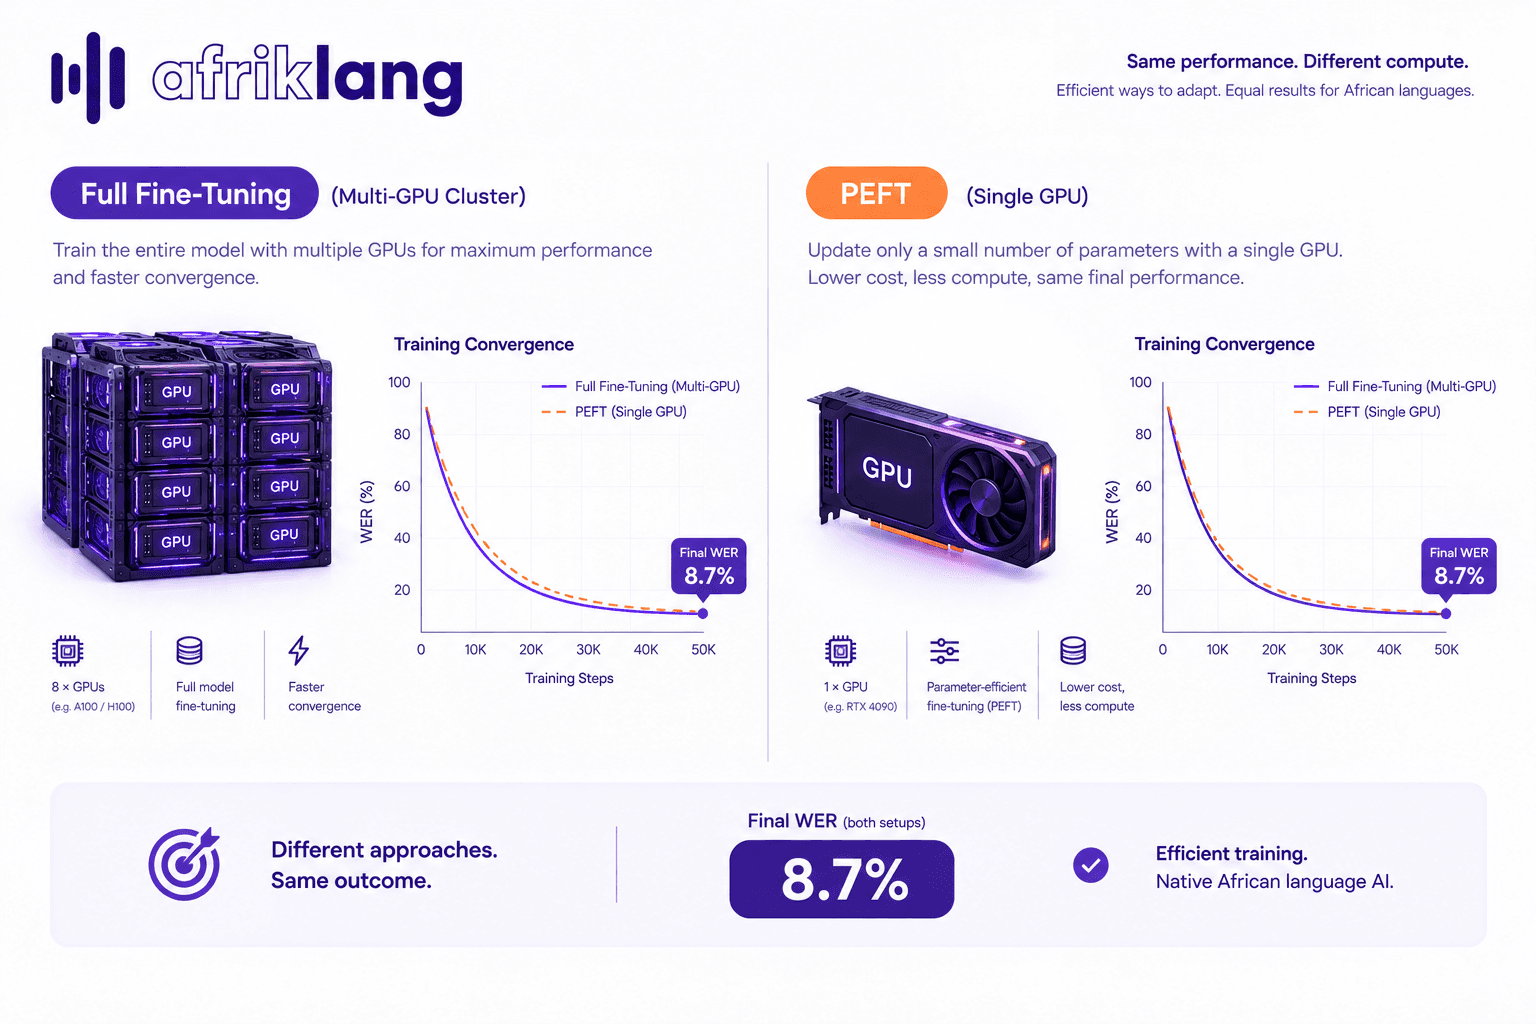
Full Fine-Tuning vs. PEFT for African Language ASR: When 10 Hours of Data Is Enough
New research shows LoRA matches full fine-tuning on Whisper-Small with just 10 hours of Hausa, Yoruba, and Igbo data—at 10% of the compute cost.
Read article
Synthetic Speech Data for African Languages: What CLEAR Global's 18-Month Study Means for Your ASR Budget
CLEAR Global's Gates-funded study found synthetic voice data improved low-resource African ASR by only ~6% WER—insufficient for production. Here's what that means for your data budget.
Read articleFine-Tuning Whisper for African Languages: The 2026 Cost and Compute Reality
GPU hours, training data volumes and engineering effort for Whisper fine-tuning on African languages—plus when commercially licensed data beats building from scratch.
Read article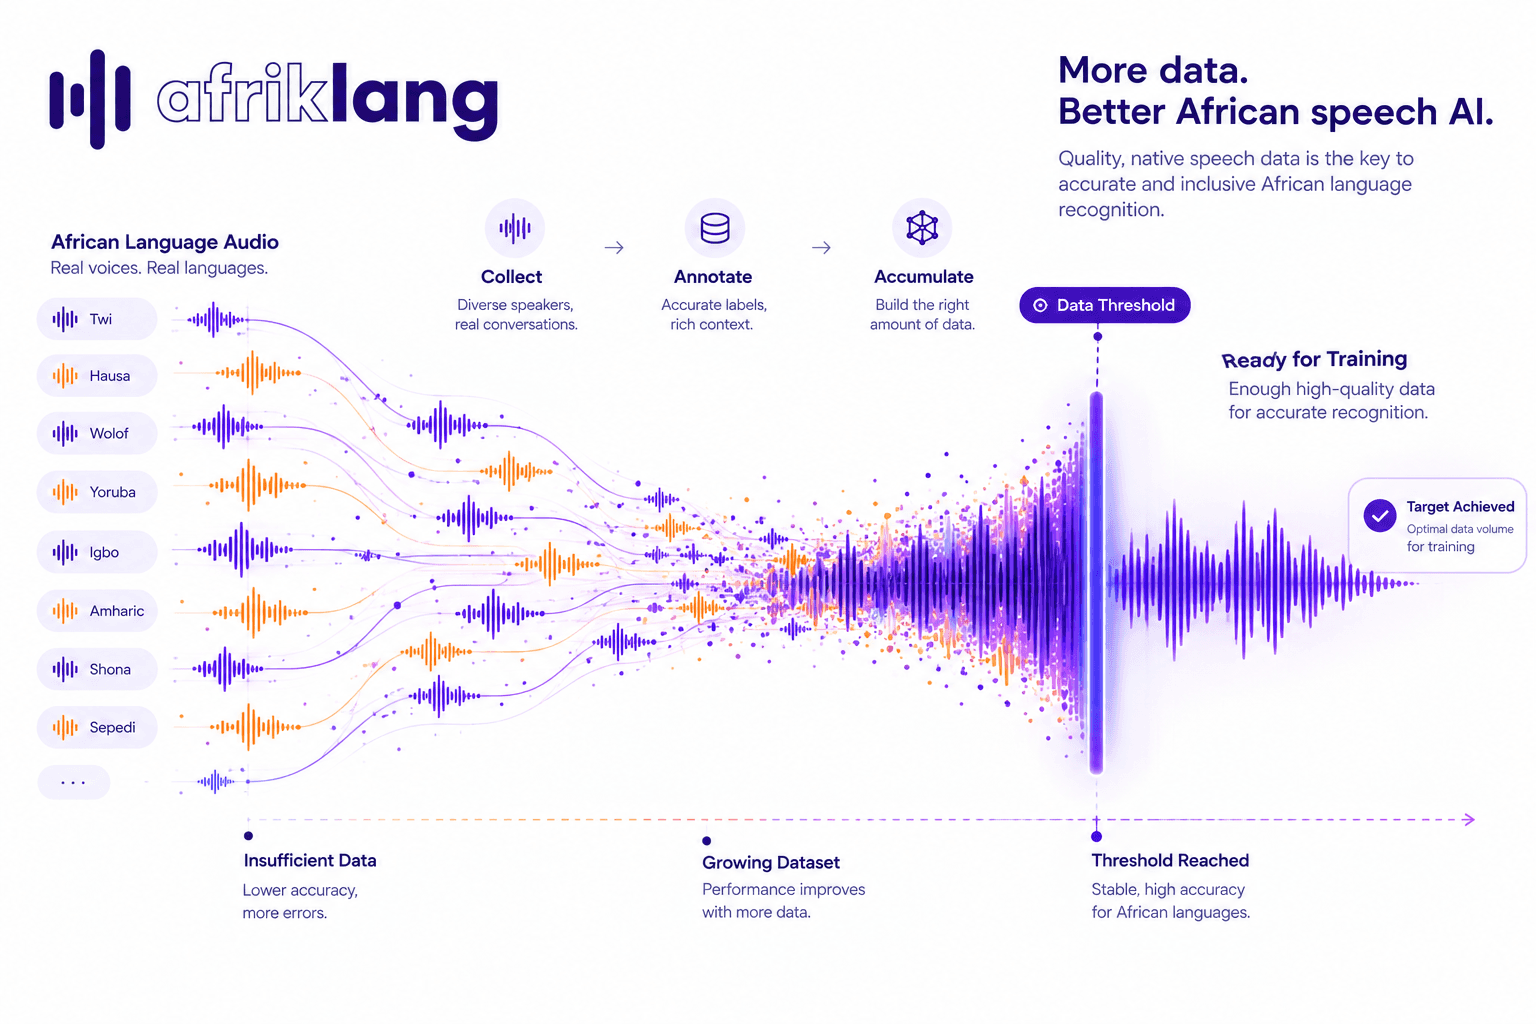
How Much Speech Data Do You Really Need? The 100-Hour Threshold for African Language ASR
New 2026 research converges on a critical number: 100-200 hours of quality data to fine-tune ASR for African languages. Here's what that means for your budget.
Read article
How to Build Domain-Specific ASR for African Languages: The Healthcare Vertical Playbook
YUX Design cut Wolof maternal health ASR error rates by 50% with just 750 utterances. Here's the engineering playbook for vertical adaptation.
Read article
Intron's Sahara-v2 and the 2026 Africa Voice AI Report: What the 57-Language Release Means for CPaaS Teams
Intron's March 2026 launch of Sahara-v2 covers 57 African languages. We break down what the release and their market report mean for production teams.
Read article
PazaBench vs. Production: What Microsoft's 39-Language ASR Benchmark Means for African CPaaS Teams
Microsoft's new PazaBench covers 39 African languages, but engineering leads still need to understand what benchmarks test and what they don't before deploying ASR in production.
Read article
WAXAL vs. Commercial African Language Speech Data: What the Google Release Means for Production Teams
Google's 11,000-hour WAXAL dataset is a research milestone, but its NC license blocks most commercial use. Here's what production teams need to know.
Read article
How to Evaluate Open Speech Datasets for Production African Language ASR: WAXAL, Common Voice, and Commercial Alternatives
Google's WAXAL corpus forces every team to rethink data sourcing. Here's the licensing, quality, and integration checklist you need before committing.
Read article
Why Common Voice Isn't Enough for Commercial African Language AI
Common Voice is a remarkable open-source corpus - but its license and coverage make it unsafe to ship in commercial African language products. Here's the commercially licensed alternative.
Read article
Upcoming articles
- Coming soon
Wolof Speech Recognition: The Training Data Problem for Senegal's CPaaS Market
Why Wolof speech recognition training data is scarce, why scraped data breaks in production, and how commercially licensed Wolof speech data closes the gap.
- Coming soon
The 60% Engineering Tax: Why African Language Data Collection Is Breaking AI Teams
AI teams spend up to 60% of their budget collecting African language data instead of building product. Here's where that engineering cost goes - and how to eliminate it.
- Coming soon
Fair-Trade Speech Data: What It Means and Why It Matters for African AI
Fair-Trade speech data means native speakers are compensated fairly for their voice. Here's what the standard means and why it matters for African language AI.
- Coming soon
Afriklang Joins the MEST Africa AI Startup Program
Afriklang has been selected for the MEST Africa AI Startup Program. Here is what incubation by one of the continent's leading tech entrepreneur programs means for our customers, partners and contributors.