Building the data infrastructure layer for African language AI
Afriklang builds the data infrastructure for African language AI commercially licensed, speaker-verified speech datasets for the AI teams training models that must work in African languages, with a growing corpus led by Luganda, Ewe, Fulfulde, and Hausa and scaling on demand.
What we stand for
Commercial-grade by default
Every dataset ships with a commercial license and an SLA no legal grey zones when you deploy at scale.
Fair-Trade sourcing
Native speakers are compensated fairly through our points-based micro-work system. Good data starts with fair work.
Linguistic rigor
Every transcript is corrected by a native speaker, and a sample of every batch is blind double-annotated to hold a ≥95% inter-annotator agreement standard.
How we build the data
Every dataset runs through the same controlled pipeline quality is engineered in at capture, not patched at the end.
Natural speech capture
Native speakers read aloud, speak spontaneously and hold conversations, so we capture the language as it's actually spoken, code-switching included.
AI quality-filtering at capture
Noisy or low-quality audio is discarded automatically before it ever reaches a human reviewer.
Native annotation & IAA cross-check
Every transcript is corrected and labeled by native speakers, and a sample of every batch is blind double-annotated to hold ≥95% inter-annotator agreement.
Benchmarked & delivered
We evaluate against Whisper and MMS baselines and deliver via API or S3 under a commercial license and SLA.
The people behind Afriklang
A team spanning operations, business, AI and linguistics incubated in the MEST Africa AI Startup Program.
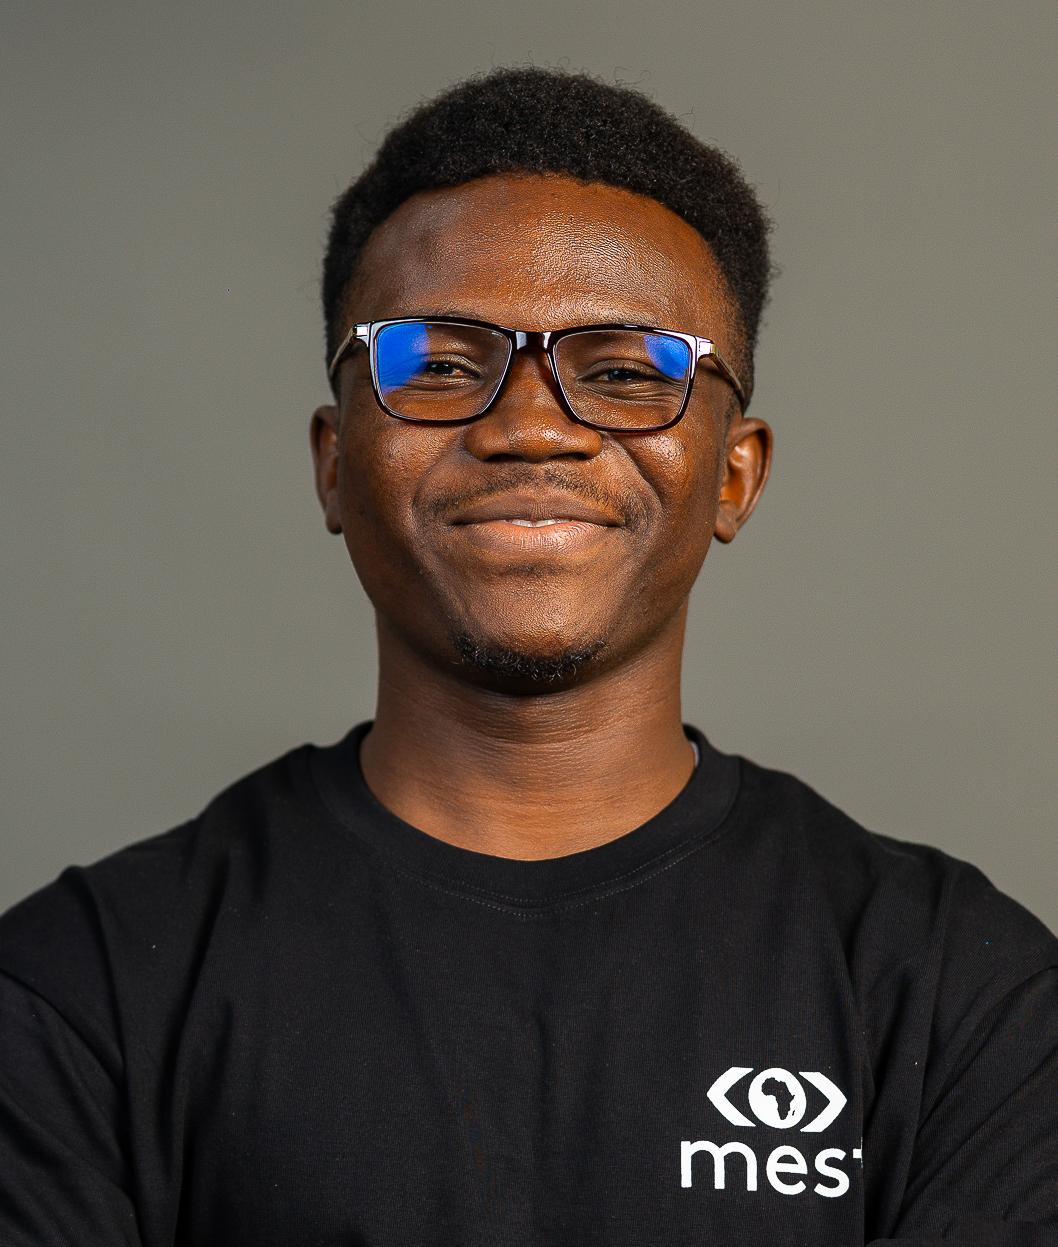
Agnilonda Pakou
CEO
Leadership
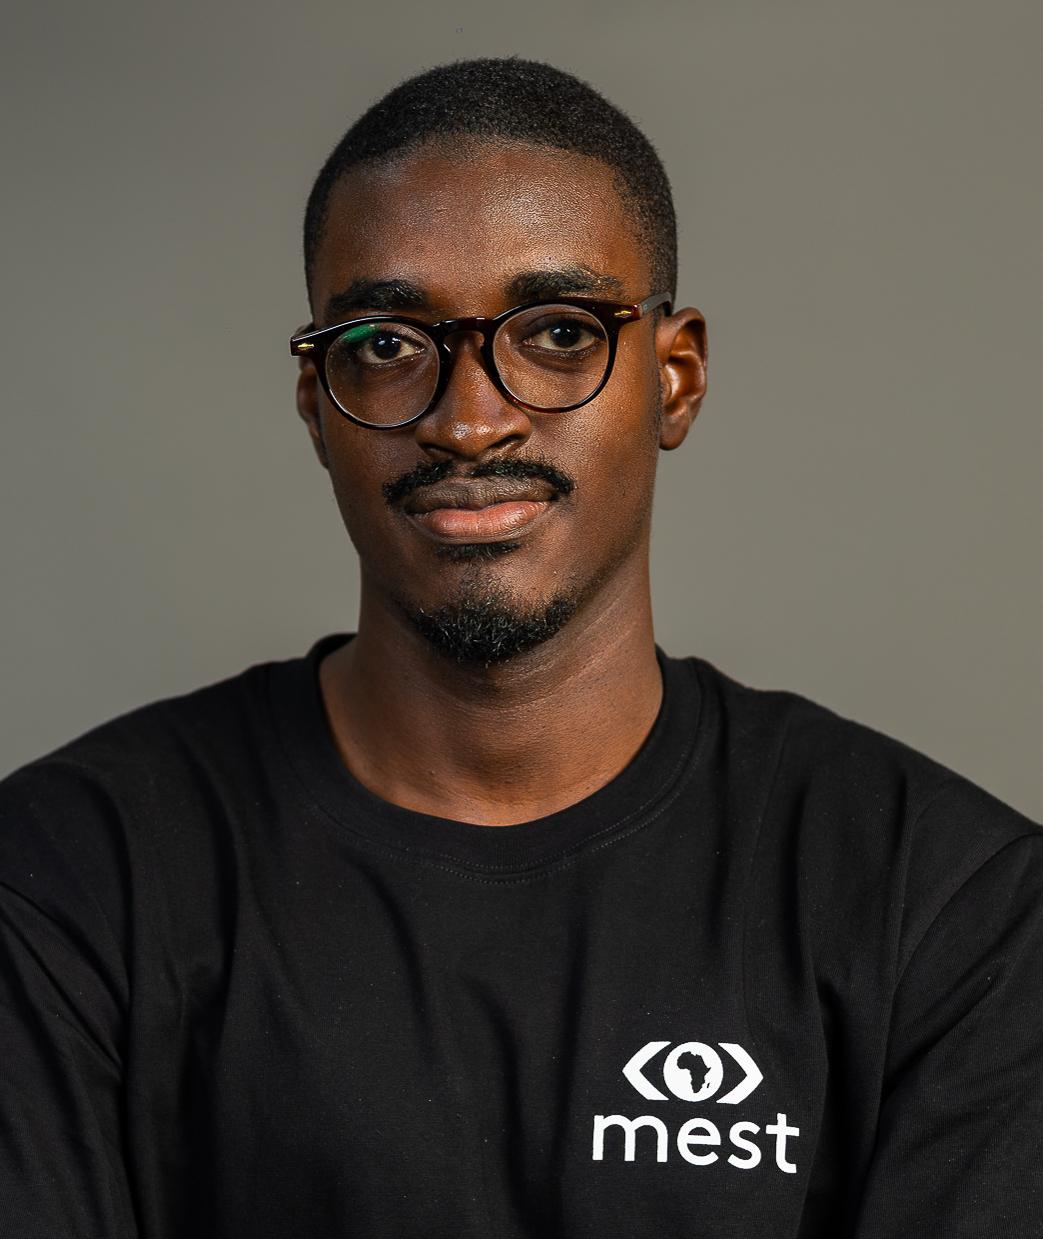
Khalifa Niamadio Mamadou
COO
Operations
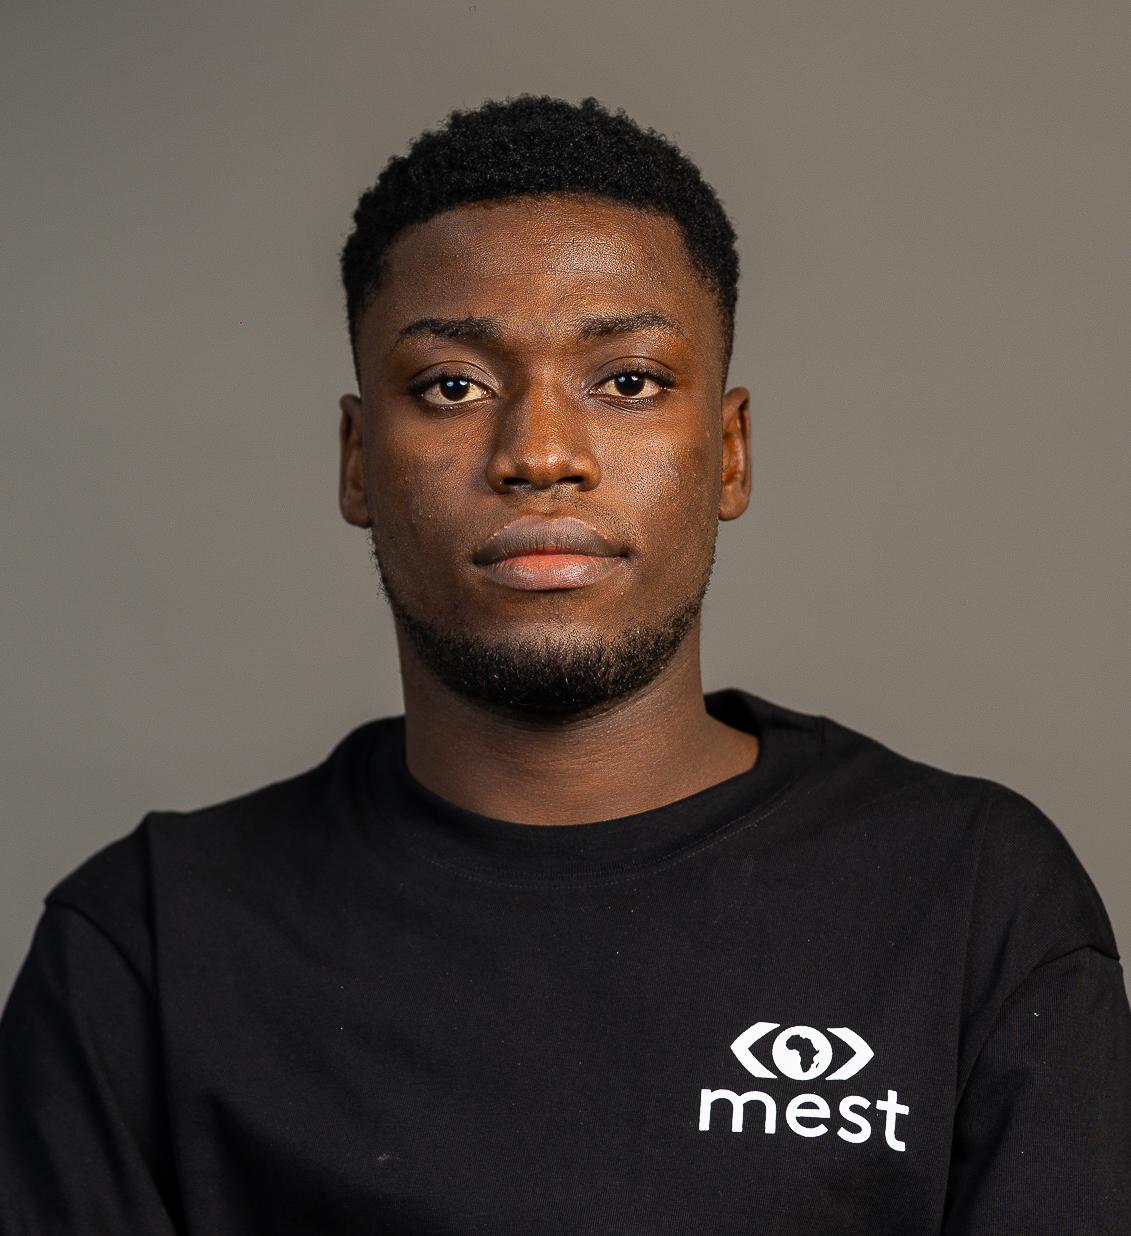
Mahougnon Fredy Houndayi
Chief AI Officer
AI & Engineering
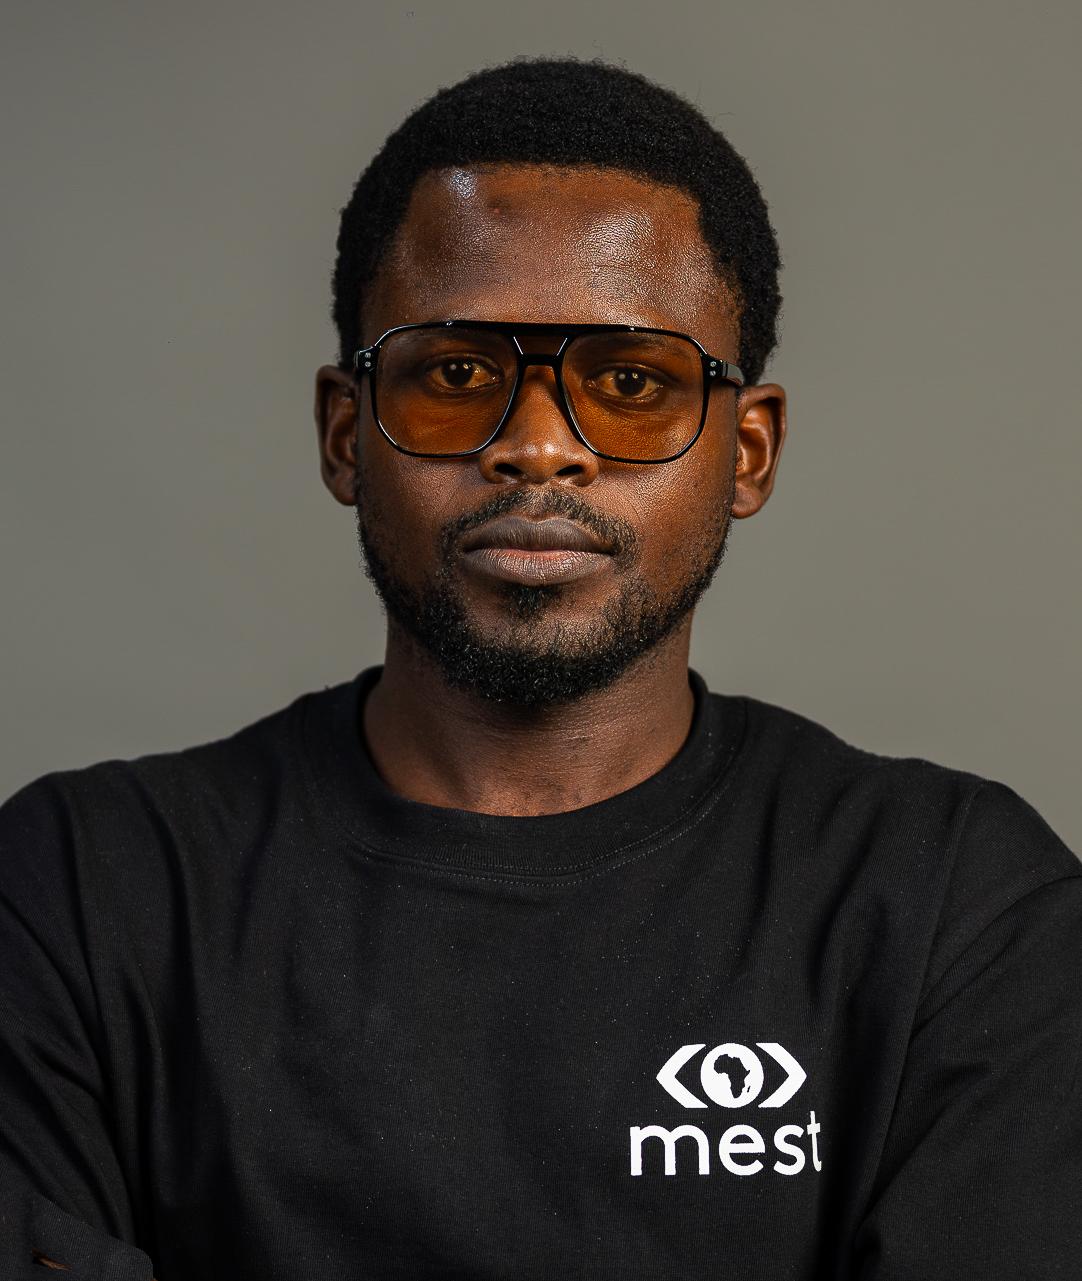
Babacar Ndao
Chief Data Officer
Data & Linguistics


Incubated in the MEST Africa AI Startup Program
Afriklang is backed by MEST Africa and incubated in its AI Startup Program one of the continent's leading technology entrepreneur programs and investors, giving our data pipeline hands-on support and a pan-African network.
Let's build African-language AI together.
Or email us at contact@afriklang.com